Self-hosting a high-availability Postgres cluster on Kubernetes
View the Hacker News discussion
Large cloud providers do indeed go down and without carefully architecting your systems to handle the scenario of when they go down, not if they go down, you need to have automated service failover integrated into your system design process to ensure maximal uptime of your most critical applications. 2023 was a fun year for incidents, let's have a look at just a few I cherry-picked below.
- Google Cloud Paris Data Center Fire (April 25, 2023)
- AWS us-east-1 Outage (June 13, 2023)
- Microsoft Azure South East Asia Outage (February 9, 2023)
- Microsoft Azure West Europe Outage (July 5, 2023)
- Microsoft Azure Australia Outage (August 30, 2023)
If you're not convinced or feel like you want to study the topic of high-availability more, you should check out this fantastic article from Cockroach Labs (creators of CockroachDB).
As I've invested more in standardizing hosting my applications on Kubernetes, I started to think about shifting my database into Kubernetes as well to centralize how I manage all my services in one place. While this topic doesn't come without heavy debate, I think we've evolved to a point where supporting this hosting paradigm is pretty streamlined.
By the end of this article we will have:
- Setup a highly-available and fault tolerant Postgres cluster from scratch
- Host a UI to manage the clusters
- Create a database and test disaster recovery by killing nodes
If you see me issue the command
k, it's a custom alias mapped in my~/.zshrcthat maps tokubectl. I'll often just typekfor brevity.
Zalando Postgres operator
Zalando is a Postgres operator that facilitates the deployment of a highly available (HA) Postgres cluster. Zalando uses Patroni under the hood, which is essentially a template for scaling HA Postgres clusters.
Key features of the Zalando Postgres Operator include:
- Rolling updates on Postgres cluster changes, including quick minor version updates.
- Live volume resize without pod restarts (for certain storage types like AWS EBS and PVC).
- Database connection pooling with PGBouncer
Let's start by deploying the Zalando operator to our cluster followed by the Postgres cluster itself. We will be heavily referencing the documentation moving forward.
To keep things raw, we will use the manifests directly with kubectl.
# First, clone the repository and change to the directory
git clone https://github.com/zalando/postgres-operator.git
cd postgres-operator

# apply the manifests in the following order
kubectl create -f manifests/configmap.yaml  # configuration
kubectl create -f manifests/operator-service-account-rbac.yaml  # identity and permissions
kubectl create -f manifests/postgres-operator.yaml  # deployment
kubectl create -f manifests/api-service.yaml  # operator API to be used by UI
I recommend reading each one of these manifests thoroughly to ensure compatibility with your cluster.
You can validate everything is running with kubectl get pod -l name=postgres-operator.
NAME                                READY   STATUS    RESTARTS   AGE
postgres-operator-77f6d658c-mnlj6   1/1     Running   0          37s
Zalando management UI (optional)
Zalando provides a UI out of the box which is incredibly easy to deploy.
# using kubectl
kubectl apply -f ui/manifests/

# or using Helmcharts
# helm install postgres-operator-ui ./charts/postgres-operator-ui
You can validate the deployment is running by grepping for the pods.
❯ kubectl get pods | grep -i postgres-operator-ui
postgres-operator-ui-7bf9676b84-824j6   1/1     Running   0          28m
Since I don't plan on exposing this, we can quickly crack it open with using kubectl port-forward.
kubectl port-forward deploy/postgres-operator-ui 9090:8081From here, we should be able to access the UI via http://localhost:9090.
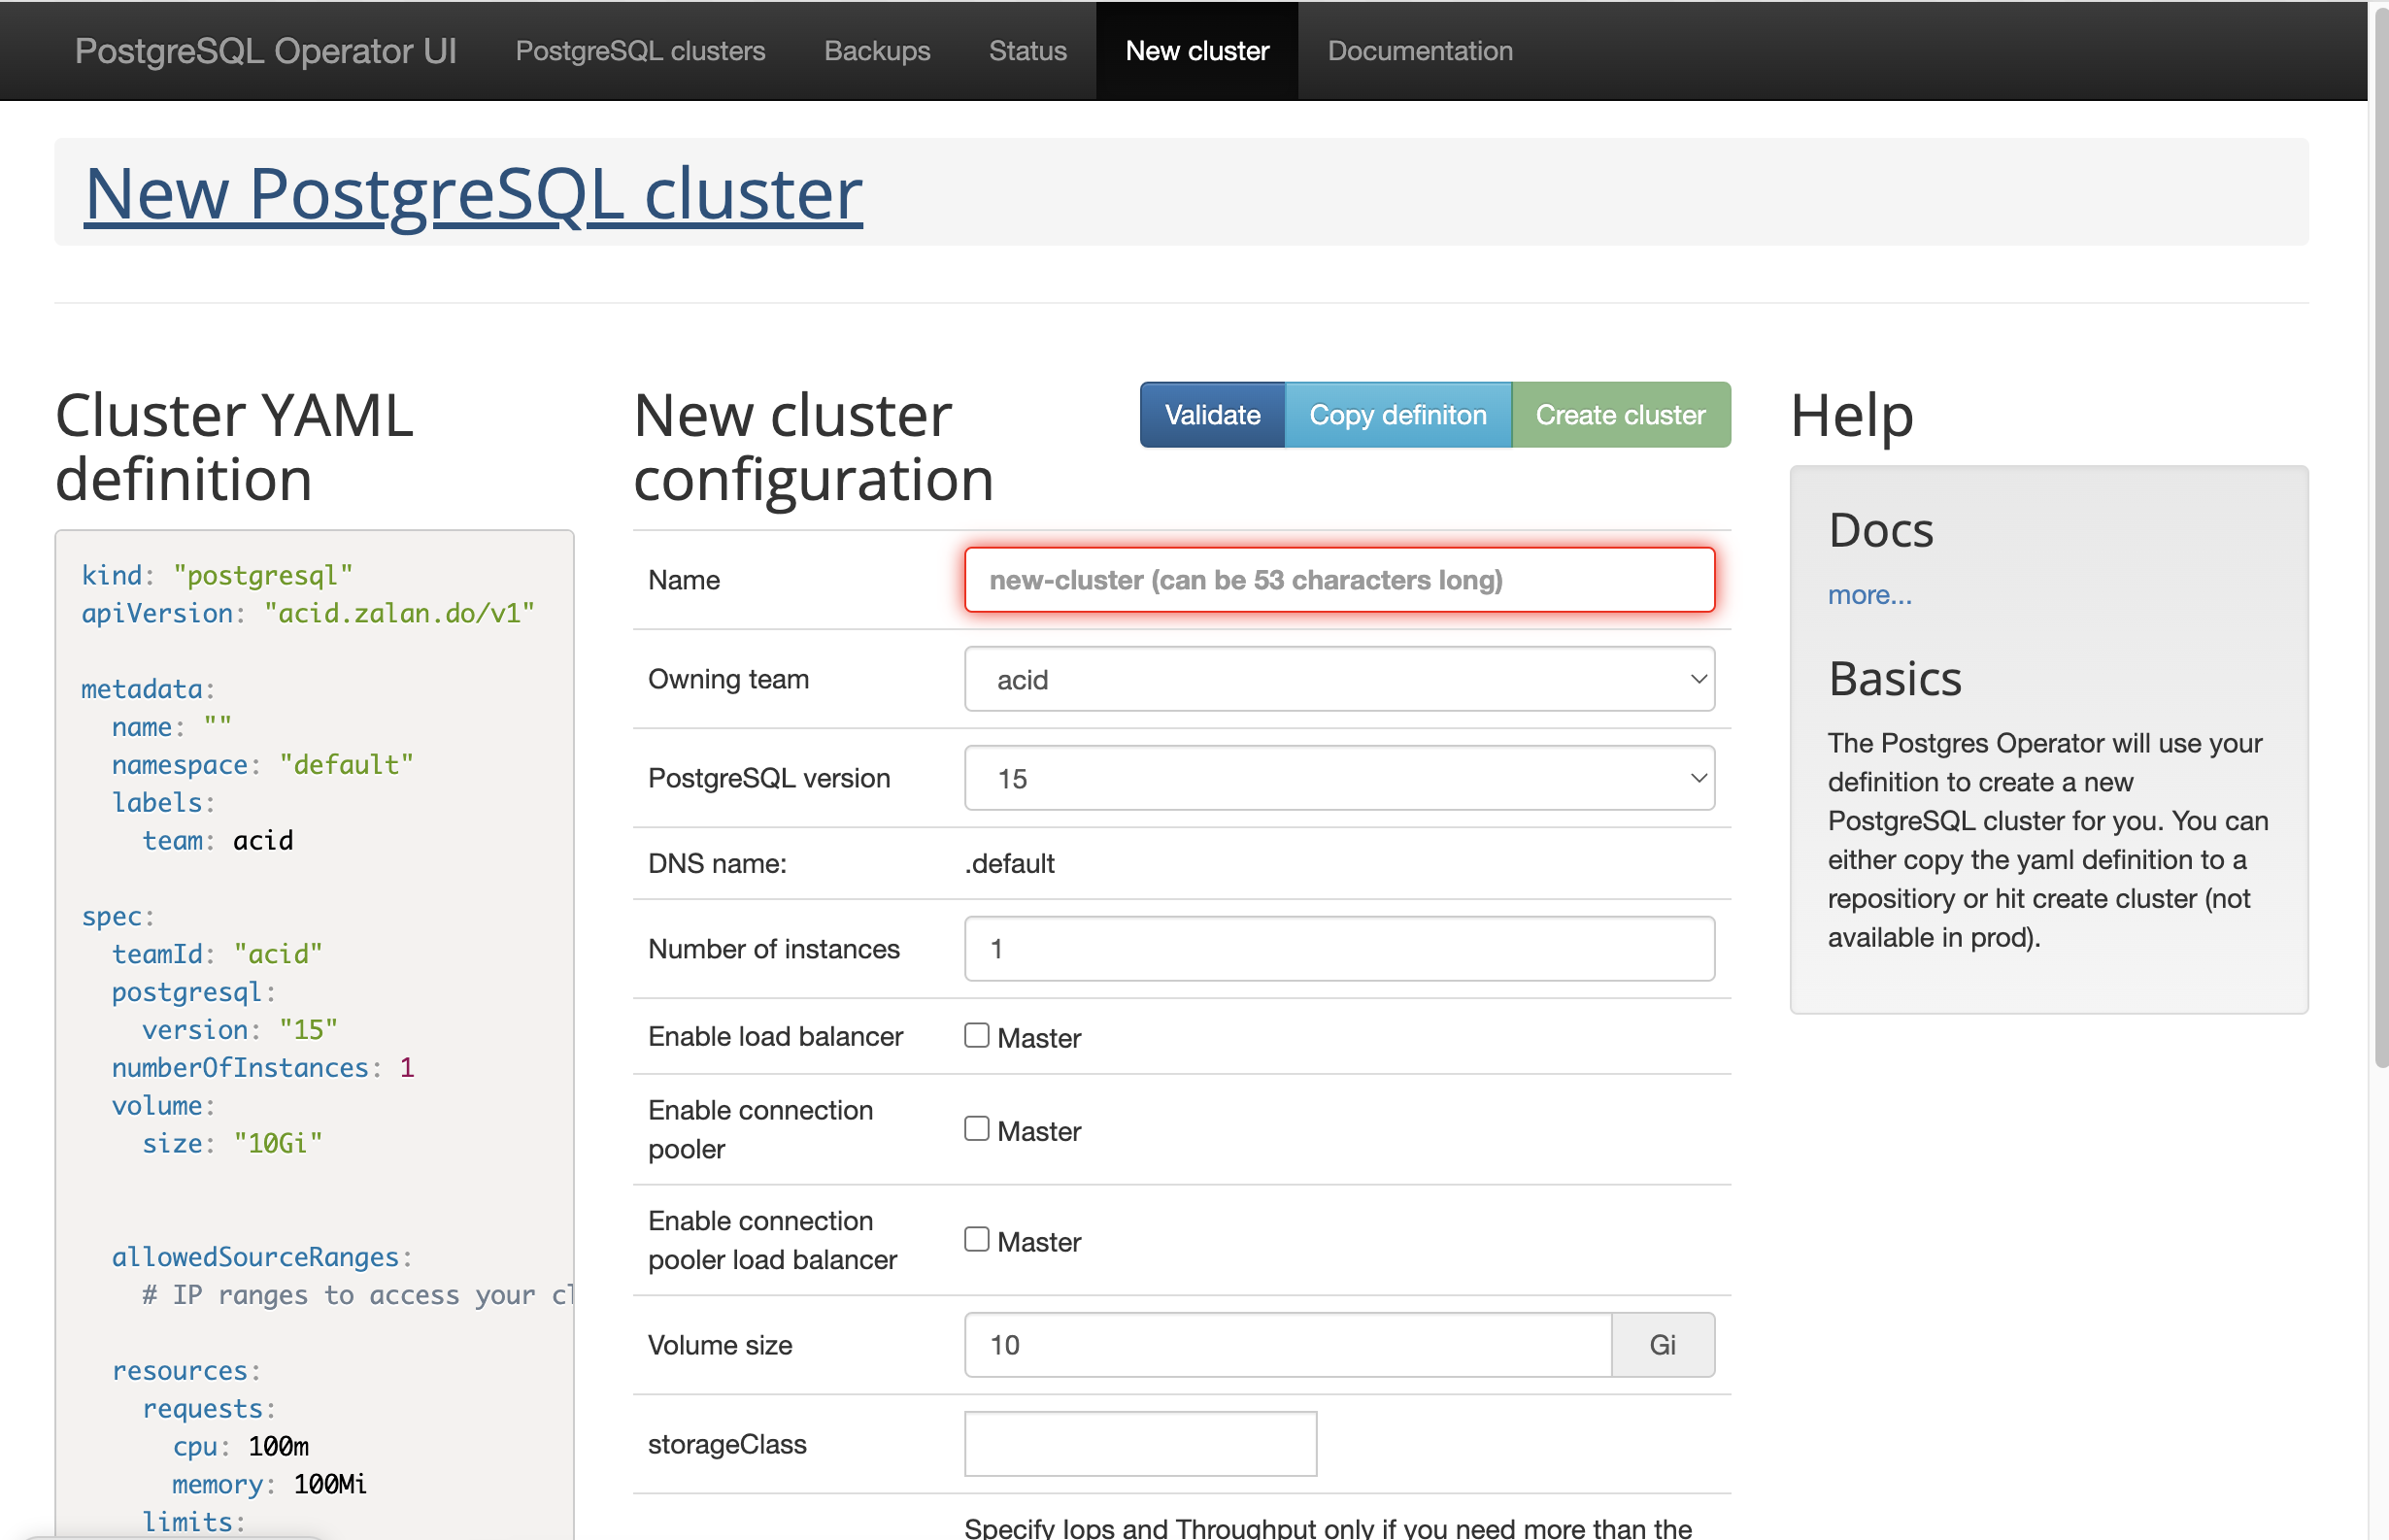
Moving forward, I will not be using the UI, but it's available if you prefer it.
Postgres cluster deployment
We will still be leveraging Zalando for deploying the Postgres cluster as well. You can view more options in the complete manifest example YMLor the parameter overview here.
I have 3 nodes in my cluster and I want 2/3 to actually run the operator (node2 and node3). Before configuring the affinity to do this, we need to label our data plane nodes. The label here is arbitrary.
kubectl label nodes node2 pg-replication=true
kubectl label nodes node3 pg-replication=true
In my case, I'm just going to schedule on my worker nodes. using node-role.kubernetes.io/worker=worker.
Now we should be able to apply the postgres resource to our cluster.
apiVersion: "acid.zalan.do/v1"
kind: postgresql
metadata:
  name: pg-cluster
spec:
  teamId: "homelab"
  volume:
    size: 20Gi
    storageClass: local-path
  enableMasterLoadBalancer: true
  numberOfInstances: 2
  users:
    schachte:
    - superuser
    - createdb
  postgresql:
    version: "15"
  nodeAffinity:
    requiredDuringSchedulingIgnoredDuringExecution:
      nodeSelectorTerms:
        - matchExpressions:
            - key: node-role.kubernetes.io/worker
              operator: In
              values:
                - worker
Note: I have
Longhorninstalled on my cluster, so mystorageClassmay be different than yours. Feel free to omit thestorageClasskey or validate what class to use viakubectl get storageClass.
There are a couple important things to point out that are subtle.
numberOfInstancestotal number of instances for a given cluster. The operator parametersmax_instancesandmin_instancesmay also adjust this number. Required field.enableMasterLoadBalancerboolean flag to override the operator defaults (set by theenable_master_load_balancerparameter) to define whether to enable the load balancer pointing to the Postgres primary. Optional.sizewill be the amount allocated for each instance. In this case, we will allocate a total of 40Gi of storage.
In this case we have 2 running clusters that will sync with one another. The clusters will be running on 2 separate nodes due to the nodeAffinity selector.
# view allocated storage
❯ k get pv

NAME                                       CAPACITY   ACCESS MODES   RECLAIM POLICY   STATUS   CLAIM                         STORAGECLASS   REASON   AGE
pvc-913d0700-ae39-4be5-96e6-afddf86ae64a   20Gi       RWO            Delete           Bound    default/pgdata-pg-cluster-0   local-path              8m3s
pvc-efec9b6a-24d1-46ff-9039-749d6e72841c   20Gi       RWO            Delete           Bound    default/pgdata-pg-cluster-1   local-path              7m56s
Great, each node has a 20Gi replica of the DB in case one of the nodes dies, the data consumers shouldn't notice any degradation.
# view running K8s services
> k get svc

# omitting other services for brevity
...
pg-cluster             LoadBalancer   10.43.112.7     192.168.70.10,192.168.70.20,192.168.70.30   5432:32461/TCP   10m
Alas the benefit of the enableMasterLoadBalancer parameter. Since I'm running on a bare-metal server, this param allocates me the node private IPs as the externally accessible addresses instead of just the internal clusterIP.
> k get pods

# omitting other pods for brevity
postgres-operator-77f6d658c-mnlj6       1/1     Running   0          78m
postgres-operator-ui-7bf9676b84-824j6   1/1     Running   0          76m
pg-cluster-1                            1/1     Running   0          6m38s
pg-cluster-0                            1/1     Running   0          6m19s
In total we have:
- Postgres operator for managing the cluster
- Postgres operator UI
- Cluster 0 running on node 2
- Cluster 1 running on node 3
Connecting to the database
Let's connect to the DB. You can use whatever client you like, in my case I'll use PGAdmin, but psql or something similar would suffice.
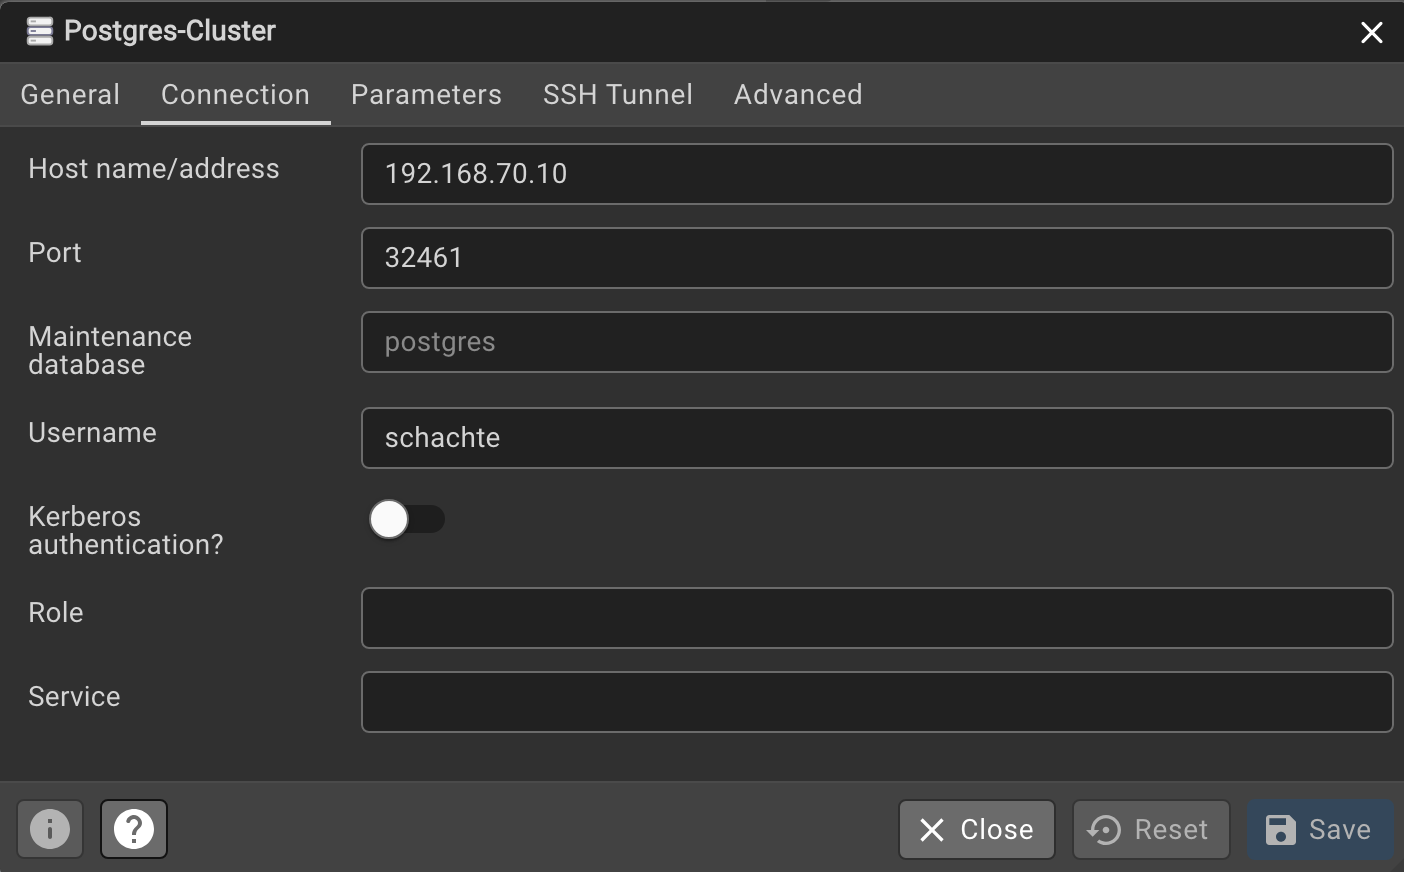
Typically you would have a load balancer IP that balances across your nodes running Postgres, but we'll validate with just a couple nodes independently and validate the data is replicated.
The password is auto generated and placed in a K8s secret. View it with:
# find the secret for the user you specified
k get secrets

# export the secret to stdout and base64 decode it so we can use within our DB client
kubectl get secret schachte.pg-cluster.credentials.postgresql.acid.zalan.do -o jsonpath="{.data.password}" | base64 --decode
I'm going to create a blog database and add a comments table with dummy data as our starting point.
CREATE TABLE comments (
  id SERIAL PRIMARY KEY,
  email VARCHAR(255) NOT NULL,
  date TIMESTAMP NOT NULL,
  name VARCHAR(255) NOT NULL,
  comment TEXT NOT NULL
);

-- Insert 20 dummy records
INSERT INTO comments (email, date, name, comment)
SELECT
  md5(
    random():: text
  ):: varchar(255) AS email,
  TIMESTAMP '2024-01-01' + (
    random() * (
      TIMESTAMP '2024-12-31' - TIMESTAMP '2024-01-01'
    )
  ) AS date,
  md5(
    random():: text
  ):: varchar(255) AS name,
  md5(
    random():: text
  ):: varchar(255) AS comment
FROM
  generate_series(1, 20);
This will push 20 dummy records into the comments table.
Failover test
We won't deploy any crazy chaos testing automation, but we will simulate node failure to ensure failover is working without degradation. In my case, I have 2 nodes:
❯ k describe pod/pg-cluster-1 | grep -i "Node:"
Node:             node2/192.168.70.20

❯ k describe pod/pg-cluster-0 | grep -i "Node:"
Node:             node3/192.168.70.30
If we delete pg-cluster-1 using k delete pod/pg-cluster-1, we should still be able to read & write to the DB. Once the node is deleted, it will be automatically scheduled to recreate itself based on the instance count specified in the Zalando deployment yaml.
Takeaways
I wouldn't deploy this directly to production, but I think it gets a very good baseline setup. I would say next important steps would be:
- metrics with Prometheus
- alerting via ntfy
- better load balancing across nodes