Observability and experimentation with ephemeral network clusters
I recently purchased 3 x Lenovo ThinkCentre M920q servers to use for my homelab cluster which runs Kubernetes and a bunch of containers for self-hosting open-source software.
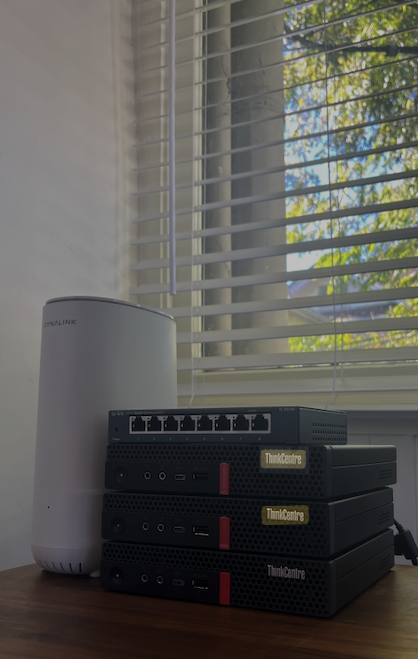
After spending a weekend routing everything up to my switch on my home network with OpenWRT I knew I wanted two things right away:
- Ability to iterate on a mock cluster without affecting the physical hardware
- Ability to observe cluster state and application state using something like Grafana & Prometheus
For the first bullet, iteration on a mock cluster is nice because one can spin up an ephemeral environment, throw a bunch of test code at it and see if it works. This is much easier than accidentally breaking production or modifying dozens of config files only to realize you made a mistake.
In order to achieve this flow, we are going to be doing the following:
- Setting up a 3-node Ubuntu cluster using Multipass virtual machines with Terraform
- Configuring Ansible playbooks and roles to install Kubernetes
- Apply a series of manifests to install Prometheus for metrics collection
- Apply a series of manifests to install Grafana for metrics visualization
- Install a community-driven dashboard to view node metrics holistically across the cluster
For context, I am using:
- M1 Apple Mac (ARM) with 16GB of RAM and 500GB of storage.
- Terraform v1.5.7
- Multipass 1.13.1+mac
Multipass & Terraform
Currently, there is a wee bit of complexity in this setup because I've modified the primary Terraform provider for Multipass as well as the underlying Go code that interfaces with Multipass directly. Luckily, I've discussed this in detail in this article. This isn't a hard requirement, but it adds some utility when trying to assign static IPs later on to each of the VMs in the cluster.
For Terraform, I like to use workspaces to segregate my environments. While this article is focusing primarily on iteration for development, we'll still create a production workspace.
.
├── environments
│   ├── dev
│   └── prod
├── main.tf
└── modules
    └── multipass
        ├── main.tf
        ├── provider.tf
        ├── templates
        │   └── cloud-init.yaml.tpl
        └── variables.tf

6 directories, 9 files
The first step is to create workspaces that allow you to operate on each environment independent of one another:
terraform workspace new devterraform workspace new prod
You can verify that worked via terraform workspace list and you can select the one you want via terraform workspace select dev.
❯ terraform workspace list

  default
* dev
main.tf
terraform {
  backend "local" {
    path = "terraform.tfstate"
  }
}

// Development machines used for Ansible testing locally
module "multipass" {
  count  = terraform.workspace == "dev" ? 1 : 0
  source = "./modules/multipass"

  instance_names = ["node1", "node2", "node3"]
  ip_addresses   = ["192.168.64.97/32", "192.168.64.98/32", "192.168.64.99/32"]
  mac_addresses  = ["52:54:00:4b:ab:bd", "52:54:00:4b:ab:cd", "52:54:00:4b:ab:dd"]
  cpus           = 2
  memory         = "2.5G"
  disk           = "5.5G"
  image          = "22.04"
}
In this setup, we're taking advantage of Terraform modules which provide a nice way to separate code and reuse code more efficiently. You'll notice in this setup, I'm specifically targeting dev as the workspace as this code configures local virtual machines for development. The variables in this case are self-explanatory and defined in variables.tf.
providers.tf
I like to keep all my provider dependencies in their own file and this currently is using my locally modified Multipass provider mentioned in the article above.
terraform {
  required_providers {
    multipass = {
      source  = "ryan-schachte.com/schachte/multipass"
      version = "1.0.0"
    }
  }
}
If you don't care about static IP assignments, you can simply just do this:
terraform {
  required_providers {
    multipass = {
      source = "larstobi/multipass"
      version = "1.4.2"
    }
  }
}
VM automation and configuration
For the VM setup, I'm leveraging the cloud-init configuration files. This just makes it easy for me to do a bunch of setup in a single file such as IP address assignment, SSH configuration, etc. Currently, the setup is super basic as I'm just adding SSH keys to enable SSH communication to the VM from the host.
#cloud-config
users:
  - name: schachte
    sudo: ALL=(ALL) NOPASSWD:ALL
    ssh_authorized_keys:
      - <REDACTED>
If we crack open main.tf in the multipass module, I leverage this template file to generate config for each node on the fly for each run of the plan. What's neat is terraform destroy will clean up these files as well since they're maintained in state.
resource "local_file" "cloudinit" {
  for_each = { for i, name in var.instance_names : name => {} }

  filename = "${path.module}/cloud-init-${each.key}.yaml"
  content = templatefile("${path.module}/templates/cloud-init.yaml.tpl", {
  })
}
While this looks less useful now, you can imagine how useful it becomes when you have variables that differ from each node. This allows for dynamic configuration at scale for things like DHCP, IP assignments, DNS, etc where the values differ between each node itself.
Unfortunately, I wanted to do the static IP assignment in cloud-init itself, but I couldn't get it to work. Therefore, I'm instead doing it after the nodes boot up and just running a script with
netplan(see below).
Let's create a multipass_instance resource that represents our VMs based on the nodes we configured in the main.tf at the root.
resource "local_file" "cloudinit" {
  for_each = { for i, name in var.instance_names : name => {} }

  filename = "${path.module}/cloud-init-${each.key}.yaml"
  content = templatefile("${path.module}/templates/cloud-init.yaml.tpl", {
  })
}

resource "multipass_instance" "dev_vm" {
  for_each = { for i, name in var.instance_names : name => {
    ip_address  = var.ip_addresses[i]
    mac_address = var.mac_addresses[i]
  } }
}
Because my provider modification enables support for static IP address/MAC address assignment, we propagate these into the resource.
resource "local_file" "cloudinit" {
  for_each = { for i, name in var.instance_names : name => {} }

  filename = "${path.module}/cloud-init-${each.key}.yaml"
  content = templatefile("${path.module}/templates/cloud-init.yaml.tpl", {
  })
}

resource "multipass_instance" "dev_vm" {
  for_each = { for i, name in var.instance_names : name => {
    ip_address  = var.ip_addresses[i]
    mac_address = var.mac_addresses[i]
  } }

  name   = each.key
  cpus   = var.cpus
  memory = var.memory
  disk   = var.disk
  image  = var.image

  cloudinit_file    = local_file.cloudinit[each.key].filename
  network_interface = "en0"
  mac_address       = each.value.mac_address

  provisioner "local-exec" {
    command = <<-EOT
      multipass exec ${each.key} -- sudo bash -c 'cat << EOF > /etc/netplan/10-custom.yaml
      network:
        version: 2
        ethernets:
          extra0:
            dhcp4: no
            match:
              macaddress: "${each.value.mac_address}"
            addresses: ["${each.value.ip_address}"]
      EOF'
      multipass exec ${each.key} -- sudo netplan apply
    EOT
  }
}
Continuing on, I'm simply pushing the variables we define into the provider. The provider is fairly straight forward as it just shells out to Multipass some CLI args with the values we define in Terraform to spin up VMs.
As you can see above, I simply multipass exec, which is sort of like running ssh into each node. I apply a netplan file that turns off DHCP and assigns the IP addresses and mac addresses we defined.
The main benefit of static IPs for local development is that we can hardcode IP assignments in our inventory files and not worry about IPs changing as we spin up and down the VMs with Multipass (they change on every teardown!).
We can spin up the VMs using Terraform via terraform apply.
  ....
  + resource "multipass_instance" "dev_vm" {
      + cloudinit_file    = "modules/multipass/cloud-init-node3.yaml"
      + cpus              = 2
      + disk              = "5.5G"
      + image             = "22.04"
      + mac_address       = "52:54:00:4b:ab:dd"
      + memory            = "2.5G"
      + name              = "node3"
      + network_interface = "en0"
    }

Plan: 6 to add, 0 to change, 0 to destroy.
You should see something like this for each node as well as the static files that will be created from the template we use for cloud-init. Type yes + <Enter>.
You should be able to see the running VMs using multipass (note the static IP assignments).
❯ multipass list
Name                    State             IPv4             Image
node1                   Running           192.168.64.90    Ubuntu 22.04 LTS
                                          192.168.64.97
node2                   Running           192.168.64.91    Ubuntu 22.04 LTS
                                          192.168.64.98
node3                   Running           192.168.64.89    Ubuntu 22.04 LTS
                                          192.168.64.99
Ansible
Ansible is an awesome way to create idempotent runbooks for installing software and configuring your nodes in a predictable way that goes beyond just a simple bash script. The goal here is to install K3s which is a minimal Kubernetes installation perfect for homelabs.
The first step is to create an inventories.dev.ini file that contains variables and groupings for all the hosts in our cluster.
[all:vars]
target_arch=arm64

[localhost]
localhost ansible_connection=local dev_config=~/k8sconfig.yaml

[localhost:vars]
master_node_ip=192.168.64.97
node_type=local

[master]
node1 ansible_host=192.168.64.97 node_type=master ansible_ssh_common_args='-o StrictHostKeyChecking=no'

[workers]
node2 ansible_host=192.168.64.98 node_type=worker ansible_ssh_common_args='-o StrictHostKeyChecking=no'
node3 ansible_host=192.168.64.99 node_type=worker ansible_ssh_common_args='-o StrictHostKeyChecking=no'

[K3s:children]
master
workers
The key here, which should make more sense as to why we defined static IPs in Terraform, is that we assign the static IP for each node that correlates to our Multipass VM instances. In my setup, I'm saying I have 1 x master node (control plane) and 2 x worker nodes (data plane).
Assuming you setup the previous step correctly and can list your VMs with multipass list, let's try and ping all the nodes with our inventory file using the built-in Ansible ping module.
ansible all -m ping -i inventory/inventories.dev.ini

localhost | SUCCESS => {
    "ansible_facts": {
        "discovered_interpreter_python": "/opt/homebrew/bin/python3.11"
    },
    "changed": false,
    "ping": "pong"
}
node2 | SUCCESS => {
    "ansible_facts": {
        "discovered_interpreter_python": "/usr/bin/python3"
    },
    "changed": false,
    "ping": "pong"
}
node3 | SUCCESS => {
    "ansible_facts": {
        "discovered_interpreter_python": "/usr/bin/python3"
    },
    "changed": false,
    "ping": "pong"
}
node1 | SUCCESS => {
    "ansible_facts": {
        "discovered_interpreter_python": "/usr/bin/python3"
    },
    "changed": false,
    "ping": "pong"
}
Roles & Playbooks
Rolesare collections of tasks and config that is designed (in theory) to be reusable between your playbooks.Playbooksare the larger picture of a system containing a series of roles.
One could say that playbooks call roles which contain tasks utilizing variables.
I like to keep playbooks simple for the main benefit being readability. For example:
---
- name: K3S
  hosts: K3s
  gather_facts: true
  roles:
    - role: k3s
      become: true
Here, I can instantly see I'm applying 1 role in this playbook and that's the k3s role. You can imagine a playbook being called observability that sets up something like Grafana and Prometheus with grafana and prometheus being separate roles.
The role for K3s is where the magic happens. My K3s role directory structure is basic.
playbooks/roles/k3s
├── tasks
│   └── main.yaml
The tasks contain each thing we want to run. I try and keep all my tasks idempotent so I can re-run the same playbook over and over without putting my system in a bad state due to multiple invocations of the playbook.
# code: language=ansible
---
- name: Install K3S Requirements
  ansible.builtin.apt:
    update_cache: true
    pkg:
      - policycoreutils
      - nfs-common
    state: present

- name: Check if K3S is already installed
  ansible.builtin.shell:
    cmd: "test -f /usr/local/bin/k3s"
  register: k3s_installed
  failed_when: false

- name: Download K3s installation script
  ansible.builtin.uri:
    url: "https://get.k3s.io"
    method: GET
    return_content: true
    dest: "/tmp/k3s_install.sh"
  when: k3s_installed.rc != 0
The first 3 tasks ensure I have the dependencies I need, ensure I don't already have K3s installed (to avoid reinstalling and wasting time on a second run) and pulling the installer script if I don't have it installed.
# code: language=ansible
---
- name: Install K3S Requirements
  ansible.builtin.apt:
    update_cache: true
    pkg:
      - policycoreutils
      - nfs-common
    state: present

- name: Check if K3S is already installed
  ansible.builtin.shell:
    cmd: "test -f /usr/local/bin/k3s"
  register: k3s_installed
  failed_when: false

- name: Download K3s installation script
  ansible.builtin.uri:
    url: "https://get.k3s.io"
    method: GET
    return_content: true
    dest: "/tmp/k3s_install.sh"
  when: k3s_installed.rc != 0

# Note that the node_type variable is set in the inventory file
- name: Execute K3s installation script [Initial Master Node]
  ansible.builtin.shell:
    cmd: 'sh /tmp/k3s_install.sh --token "{{ k3s_token_var }}" --disable=traefik --flannel-backend=vxlan --cluster-init --tls-san {{ ansible_host }}'
  vars:
    k3s_token: "{{ k3s_token_var }}"
  args:
    executable: /bin/bash
  when: node_type | default('undefined') == 'master' and k3s_installed.rc != 0

- name: Execute K3s installation script [Worker Nodes]
  ansible.builtin.shell:
    cmd: 'sh /tmp/k3s_install.sh agent --token "{{ k3s_token }}" --server https://{{ hostvars["node1"]["ansible_default_ipv4"]["address"] }}:6443'
  loop: "{{ groups['workers'] }}"
  vars:
    k3s_token: "{{ k3s_token_var }}"
  args:
    executable: /bin/bash
  when: node_type | default('undefined') == 'worker' and k3s_installed.rc != 0

- name: Fetch kubeconfig from K3s server
  ansible.builtin.fetch:
    src: /etc/rancher/k3s/k3s.yaml
    dest: ~/k8sconfig.yaml
    flat: true
  when: node_type | default('undefined') == 'master'
  changed_when: false
The following tasks are mostly pulled from the K3s documentation that I've codified into an Ansible role.
- Setup the master node using labels from the inventory file
- Setup the worker nodes using labels from the inventory file and token pulled from the master step
- Download the Kube config YAML locally to our laptop so we can connect to the cluster and deploy things to Kubernetes.
I'm not affiliated to this author, but I've read a chunk of this Ansible book by Jeff Geerling and can highly recommend it. https://www.ansiblefordevops.com/
Let's setup Kubernetes now using our new playbook and development inventory file.
ansible-playbook -i inventory/inventories.dev.ini playbooks/k3s.yamlThis will take a few minutes to get everything configured. To utilize the Kube config file to connect to the cluster, we can override the env variable locally:
export KUBECONFIG=~/k8sconfig.yamlLet's test that it worked:
I alias
ktokubectlin my~/.zshrcfor simplicity
❯ k get nodes
NAME    STATUS   ROLES                       AGE   VERSION
node1   Ready    control-plane,etcd,master   59s   v1.28.7+k3s1
node2   Ready    <none>                      51s   v1.28.7+k3s1
node3   Ready    <none>                      47s   v1.28.7+k3s1
Cluster is up and running, but how do we monitor it?
Observability
Running software is cool and all, but if we don't know how it's performing then what's the point? I'm a fan of Prometheus for metrics collection. Prometheus utilizes a pull model instead of a push model which means the server is responsible for reaching out to your nodes and applications to scrape the metrics data instead of your applications pushing to the server. This reduces some complexity when instrumenting metrics, which you can read about here.
Prometheus stores the data it collects in a time series database and allows us to express complex queries using PromQL and visualize them in open-source software like Grafana to make pretty graphs.
Installing Prometheus into Kubernetes
Installing Prometheus is done in several ways. Typically it's recommended to just use a helm chart, but I'll be a bit more verbose for learning purposes. This is inspired by this article.
k8s/prometheus
├── cluster-role.yaml
├── config-map.yaml
├── prometheus-deployment.yaml
└── prometheus-service.yaml
└── namespace.yaml
Let's first ensure we have a monitoring namespace by applying k apply -f namespace.yaml.
apiVersion: v1
kind: Namespace
metadata:
  name: monitoring
The cluster-roles.yaml will create a service account with the minimum set of permissions needed to deploy Prometheus.
apiVersion: rbac.authorization.k8s.io/v1
kind: ClusterRole
metadata:
  name: prometheus
rules:
- apiGroups: [""]
  resources:
  - nodes
  - nodes/proxy
  - services
  - endpoints
  - pods
  verbs: ["get", "list", "watch"]
- apiGroups:
  - extensions
  resources:
  - ingresses
  verbs: ["get", "list", "watch"]
- nonResourceURLs: ["/metrics"]
  verbs: ["get"]
---
apiVersion: rbac.authorization.k8s.io/v1
kind: ClusterRoleBinding
metadata:
  name: prometheus
roleRef:
  apiGroup: rbac.authorization.k8s.io
  kind: ClusterRole
  name: prometheus
subjects:
- kind: ServiceAccount
  name: default
  namespace: monitoring
k apply -f k8s/prometheus/cluster-role.yaml
The config-map.yaml defines the scrape jobs the server is responsible for running. This tells the server which nodes to hit and at what interval. The node exporter runs on each node via a daemonset. Here, we can take advantage of endpoints and filter out results by targeting anything that matches node-exporter (see below).
relabel_configsare a bit odd. You can read more about them here. It's kind of like doing amap()andfilter()in Javascript.
apiVersion: v1
kind: ConfigMap
metadata:
  name: prometheus-server-conf
  labels:
    name: prometheus-server-conf
  namespace: monitoring
data:
  prometheus.yml: |-
    global:
      scrape_interval: 5s
      evaluation_interval: 5s
    rule_files:
      - /etc/prometheus/prometheus.rules
    scrape_configs:
      - job_name: 'node'
        kubernetes_sd_configs:
          - role: endpoints
        relabel_configs:
        - source_labels: [__meta_kubernetes_endpoints_name]
          regex: 'node-exporter'
          action: keep
For local development, the deployment is pretty straight forward. I'm not using any persistent volumes here, so data is wiped on reboots. I highlight L24 below because this enables a useful trick. If you modify the scrape config in the config map, you can bypass bouncing the deployment by just hitting the Prometheus reload endpoint.
curl -X POST http://localhost:9090/-/reloadapiVersion: apps/v1
kind: Deployment
metadata:
name: prometheus-deployment
namespace: monitoring
labels:
app: prometheus-server
spec:
replicas: 1
selector:
matchLabels:
app: prometheus-server
template:
metadata:
labels:
app: prometheus-server
spec:
containers:
- name: prometheus
image: prom/prometheus
args:
- "--config.file=/etc/prometheus/prometheus.yml"
- "--storage.tsdb.path=/prometheus/"
- "--web.enable-lifecycle"
ports:
- containerPort: 9090
volumeMounts:
- name: prometheus-config-volume
mountPath: /etc/prometheus/
- name: prometheus-storage-volume
mountPath: /prometheus/
volumes:
- name: prometheus-config-volume
configMap:
defaultMode: 420
name: prometheus-server-conf
- name: prometheus-storage-volume
emptyDir: {}There are a variety of ways to expose deployments in Kubernetes. Ideally, you would use a cloud load balancer or something like metallb if working on a bare metal cluster like myself. I will simplify this by using a node port service.
apiVersion: v1
kind: Service
metadata:
  name: prometheus-service
  namespace: monitoring
  annotations:
      prometheus.io/scrape: 'true'
      prometheus.io/port:   '9090'

spec:
  selector:
    app: prometheus-server
  type: NodePort
  ports:
    - port: 8080
      targetPort: 9090
      nodePort: 30000
Let's port forward the deployment to load Prometheus in our browser.
k port-forward deploy/prometheus-deployment 9090You should now be able to load the UI at http://localhost:9090. If you get an error, make sure the context is in the correct namespace kubectl config set-context --current --namespace=monitoring.
If you recall, we added a node-exporter job. This should collect data about the Kubernetes nodes themselves (our 3 VMs). Let's deploy the node exporter.
k8s/node-exporter
├── daemonset.yaml
└── service.yaml
The daemonset will ensure we run exactly 1 instance on each node.
apiVersion: apps/v1
kind: DaemonSet
metadata:
  labels:
    app.kubernetes.io/component: exporter
    app.kubernetes.io/name: node-exporter
  name: node-exporter
  namespace: monitoring
spec:
  selector:
    matchLabels:
      app.kubernetes.io/component: exporter
      app.kubernetes.io/name: node-exporter
  template:
    metadata:
      labels:
        app.kubernetes.io/component: exporter
        app.kubernetes.io/name: node-exporter
    spec:
      containers:
      - args:
        - --path.sysfs=/host/sys
        - --path.rootfs=/host/root
        - --no-collector.wifi
        - --no-collector.hwmon
        - --collector.filesystem.ignored-mount-points=^/(dev|proc|sys|var/lib/docker/.+|var/lib/kubelet/pods/.+)($|/)
        - --collector.netclass.ignored-devices=^(veth.*)$
        name: node-exporter
        image: prom/node-exporter
        ports:
          - containerPort: 9100
            protocol: TCP
        resources:
          limits:
            cpu: 250m
            memory: 180Mi
          requests:
            cpu: 102m
            memory: 180Mi
        volumeMounts:
        - mountPath: /host/sys
          mountPropagation: HostToContainer
          name: sys
          readOnly: true
        - mountPath: /host/root
          mountPropagation: HostToContainer
          name: root
          readOnly: true
      volumes:
      - hostPath:
          path: /sys
        name: sys
      - hostPath:
          path: /
        name: root
We deploy the service on top of this to allow access from outside:
---
kind: Service
apiVersion: v1
metadata:
  name: node-exporter
  namespace: monitoring
  annotations:
      prometheus.io/scrape: 'true'
      prometheus.io/port:   '9100'
spec:
  selector:
      app.kubernetes.io/component: exporter
      app.kubernetes.io/name: node-exporter
  ports:
  - name: node-exporter
    protocol: TCP
    port: 9100
    targetPort: 9100
Once you deploy this, you should be able to load Status > Targets on the Prometheus UI and see a successful connection + scrape. This is ultimately what will allow us to pull node information into Grafana.
Installing Grafana
Grafana is a little simpler. We have two files, the data source (Prometheus) to tell Grafana where to source data from and the deployment itself.
k8s/grafana
├── deployment.yaml
└── grafana-datasource.yamlapiVersion: apps/v1
kind: Deployment
metadata:
name: grafana
namespace: monitoring
spec:
replicas: 1
selector:
matchLabels:
app: grafana
template:
metadata:
name: grafana
labels:
app: grafana
spec:
containers:
- name: grafana
image: grafana/grafana:latest
ports:
- name: grafana
containerPort: 3000
resources:
limits:
memory: "1Gi"
cpu: "1000m"
requests:
memory: 500M
cpu: "500m"
volumeMounts:
- mountPath: /var/lib/grafana
name: grafana-storage
- mountPath: /etc/grafana/provisioning/datasources
name: grafana-datasources
readOnly: false
volumes:
- name: grafana-storage
emptyDir: {}
- name: grafana-datasources
configMap:
defaultMode: 420
name: grafana-datasourcesThe main thing to be cognizant of here is the resource limits. If you have a smaller machine, you might need to drop the limits for memory and CPU. Again, I'm not using any persistent volumes here, so data is ephemeral.
The data source is small and straight forward. We can use the Prometheus service name which will resolve to the cluster IP using Kube DNS.
apiVersion: v1
kind: ConfigMap
metadata:
  name: grafana-datasources
  namespace: monitoring
data:
  prometheus.yaml: |-
    {
        "apiVersion": 1,
        "datasources": [
            {
               "access":"proxy",
                "editable": true,
                "name": "prometheus",
                "orgId": 1,
                "type": "prometheus",
                "url": "http://prometheus-service:8080",
                "version": 1
            }
        ]
    }
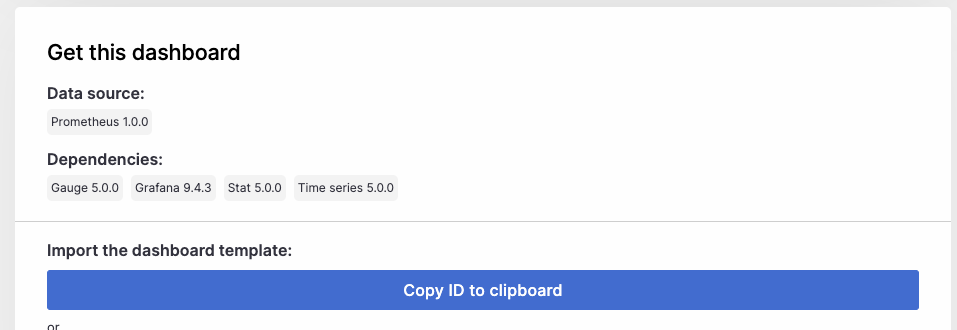
Let's port forward Grafana as well k port-forward deploy/grafana 3000. The default login is admin/admin. Now, as mentioned at the beginning, we will use a community dashboard designed to load information from the node-exporter. Simply click Copy ID to Clipboard and save it as we will import it shortly.
Verifying Prometheus connectivity
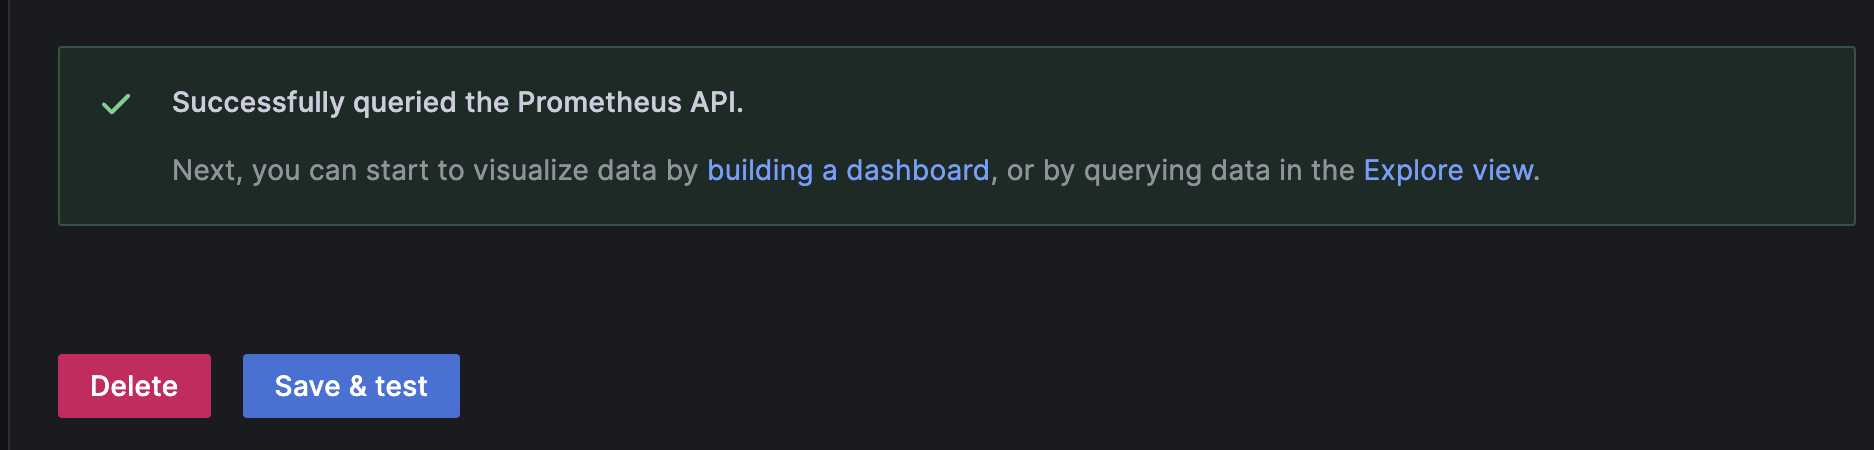
In the menu select Connections > Data Sources and hit Prometheus. If you scroll to the bottom, you can hit Save & test. This should confirm connectivity is successful.
Importing the dashboard
In the top right, select + -> Import Dashboard
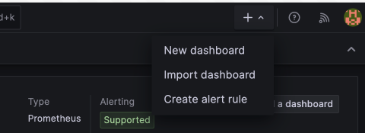
Import the dashboard by pasting the number you copied earlier.
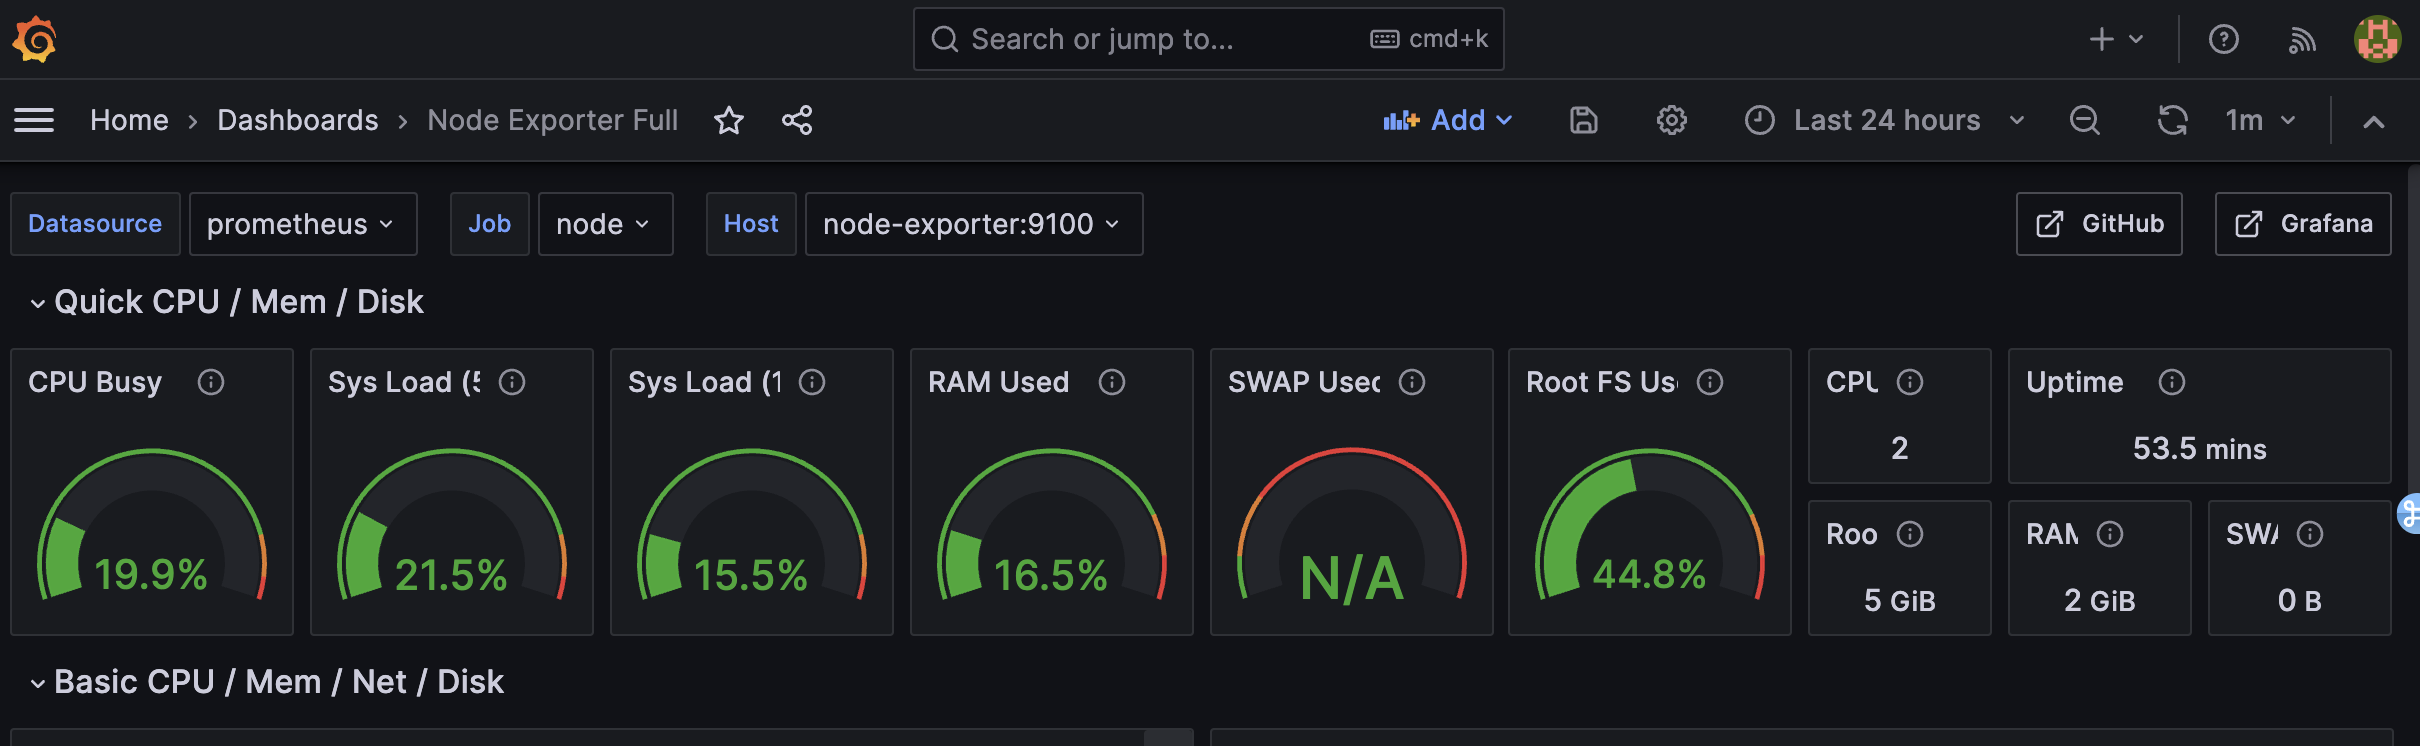
As you can see, we can now visualize our node data:
Conclusion
Having automated steps for initializing and blowing away a multi-node Kubernetes cluster is extremely useful when you want to rapidly test changes. Additionally, we can leverage tools like Prometheus and Grafana to ensure we're well aware of our software & cluster health as we make deployments, network changes and configuration updates.
For additional reading, check out alertmanager which can do things like fire alerts, integrate with pager duty, and send slack messages when certain thresholds are reached.